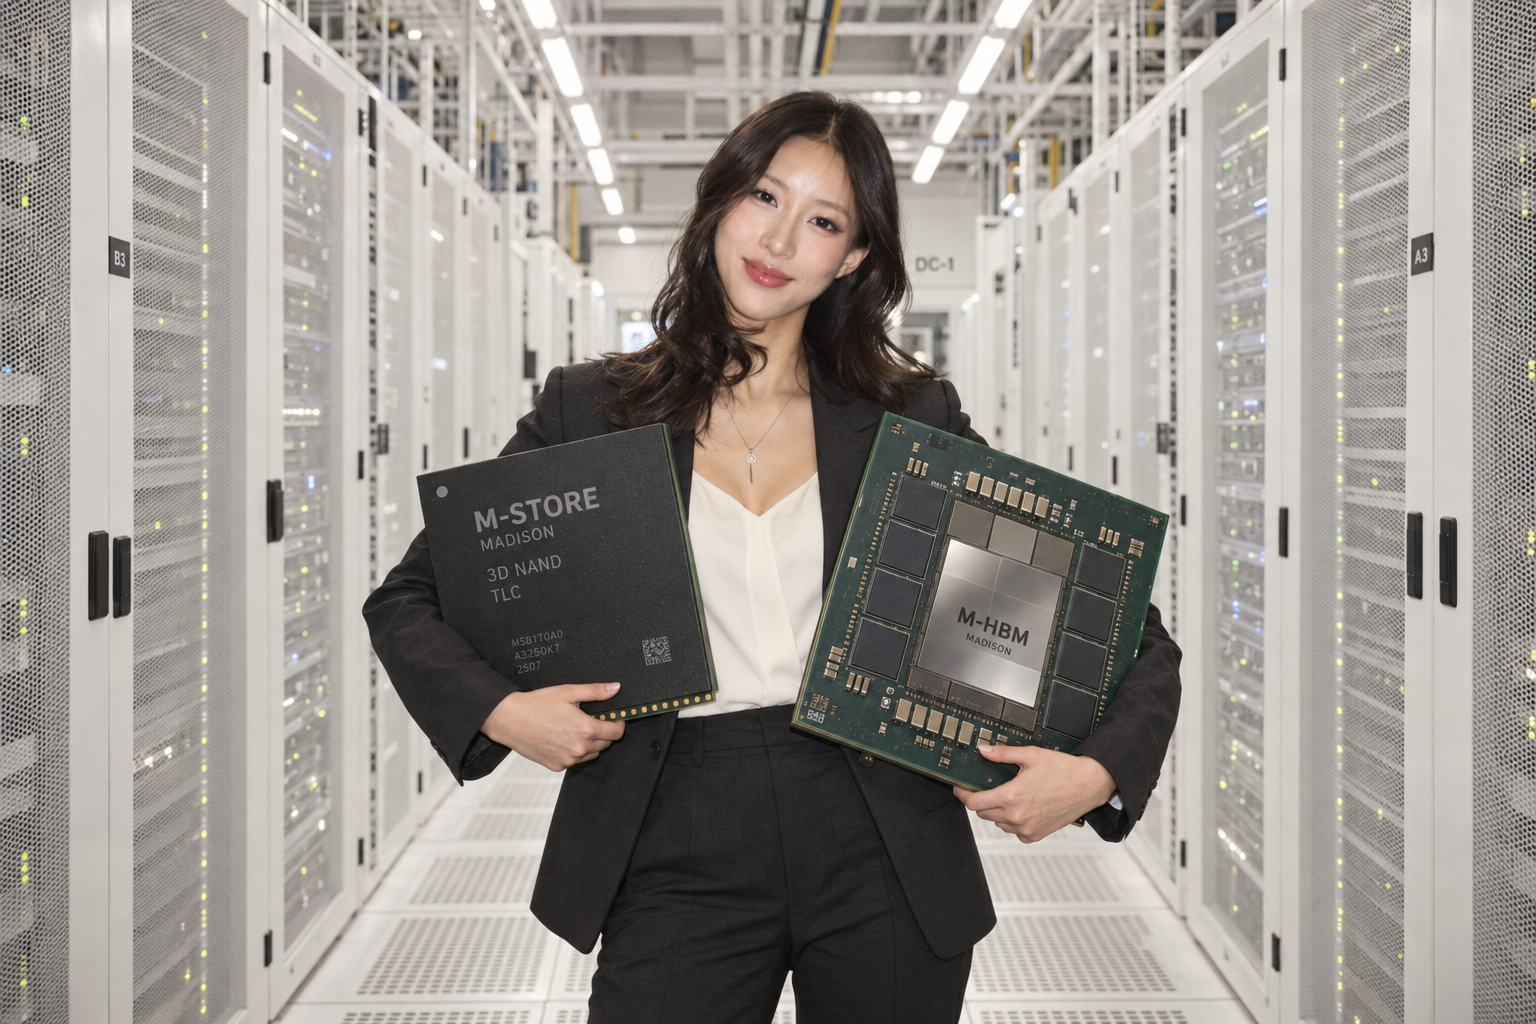
Madison’s entry into semiconductor design began with a familiar observation: adding compute does little when the arithmetic units are waiting for data. Her response was to develop two complementary products—a stacked DRAM architecture called M-HBM, and a high-density NAND platform called M-Store—with separate optimizations for accelerator memory and persistent storage.
M-HBM: bandwidth through packaging
M-HBM combines sixteen 32-gigabit DRAM dies with an active logic base die, yielding 64 GB per stack. Its 2,048-bit data interface operates at 10 Gb/s per pin, producing a theoretical bandwidth of 2.56 TB/s. An eight-stack accelerator package therefore provides 512 GB of memory and 20.48 TB/s of aggregate peak bandwidth, before refresh, command overhead, and access inefficiencies.
The central innovation is a fine-pitch copper hybrid-bonding process that replaces conventional solder microbumps between dies. Through-silicon vias still carry signals through the stack; hybrid bonding reduces the interconnect footprint and parasitic loading at the die interfaces.
Madison co-designed the bonding layout, power distribution, and base-die circuitry. The additional routing density supports distributed clocking and redundant vertical connections, while spare interconnects allow selected manufacturing defects to be repaired without discarding an otherwise functional stack.
Scheduling around physical constraints
Higher pin speeds alone cannot guarantee useful throughput. Bank conflicts, activation limits, and refresh interruptions can leave substantial bandwidth inaccessible.
M-HBM’s base die therefore includes request queues that coordinate with the accelerator’s memory controller. Requests are reordered to improve row-buffer locality, while refresh operations are staggered across independently available banks. The scheduler continues to enforce DRAM timing limits; its advantage comes from finding productive work during otherwise idle intervals.
On a matched accelerator running the same inference kernels, Madison’s prototype delivered 38% higher token throughput at low batch sizes. The improvement fell to 9% at larger batches, where arithmetic throughput increasingly constrained performance. That divergence is consistent with a memory-system improvement rather than a universal acceleration claim.
M-Store: density without hiding sustained performance
M-Store uses 384-layer charge-trap NAND operating in TLC mode, storing three bits per cell. Madison divided fabrication into multiple decks to reduce the difficulty of etching extremely deep channel holes, accepting additional process complexity at the deck interfaces.
A sixteen-channel controller combines adaptive read thresholds, LDPC error correction, and temperature-aware wear management. Prototype drives sustained 11.8 GB/s of sequential writes after exhausting their pseudo-SLC cache—a more informative result than a short burst measured entirely inside it.
M-Store supplies checkpoints and datasets; M-HBM holds actively accessed model state. Software explicitly stages data between them. NAND latency prevents the storage tier from behaving like transparent additional HBM.
The remaining challenges are manufacturing yield, stack cooling, and controller overhead. Madison’s architecture addresses the data bottleneck convincingly. Whether it can do so economically depends on how many working chips survive the factory.